Pelican benchmark · v2 refresh · updated 2026-09-28
Can a coding agent draw a pelican riding a bicycle?
We gave 14 agent and model pairs the same Jetty runbook: hand-write an SVG of a pelican on a bicycle, look at the render, score it, and redraw it. Then we let each one hill-climb for several rounds. The v2 refresh adds five current models and an external vision judge, because the agents' own scores turned out to be generous.
Agent × model lineages
14
9 from v1 · 5 new in v2
Hill-climb rounds
98
each one a Jetty trajectory
Top judge score
32.8/40
opencode · Gemini 3.8 Flash
Median self-score inflation
+9.6
points the agents award themselves over the judge
New in v2 · 5 current models on Jetty
The v2 lineup
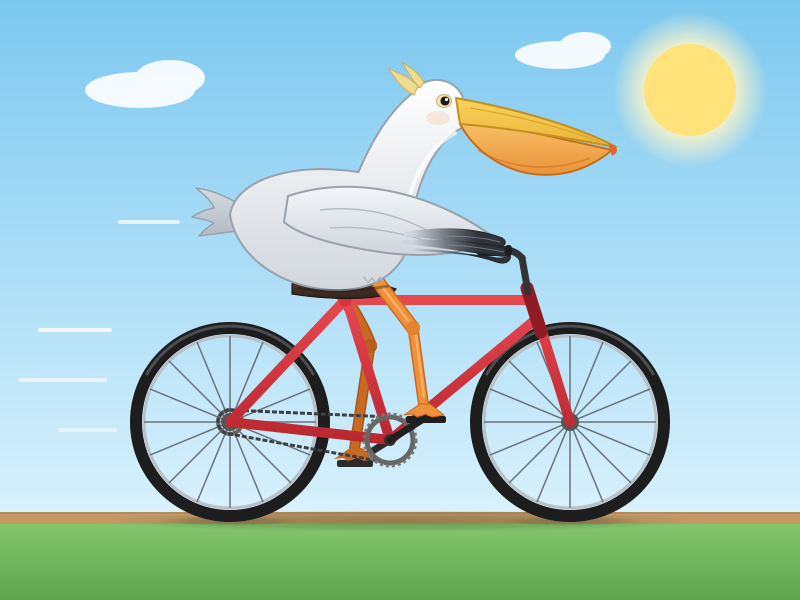
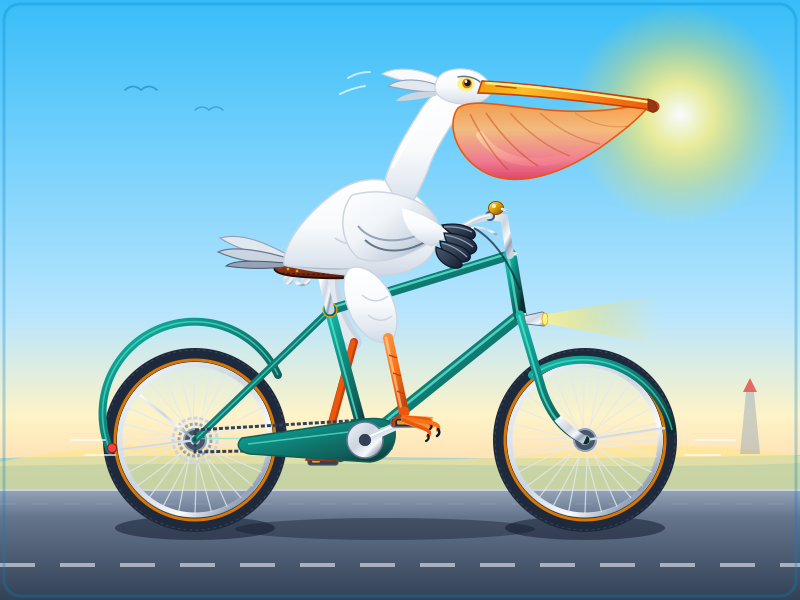
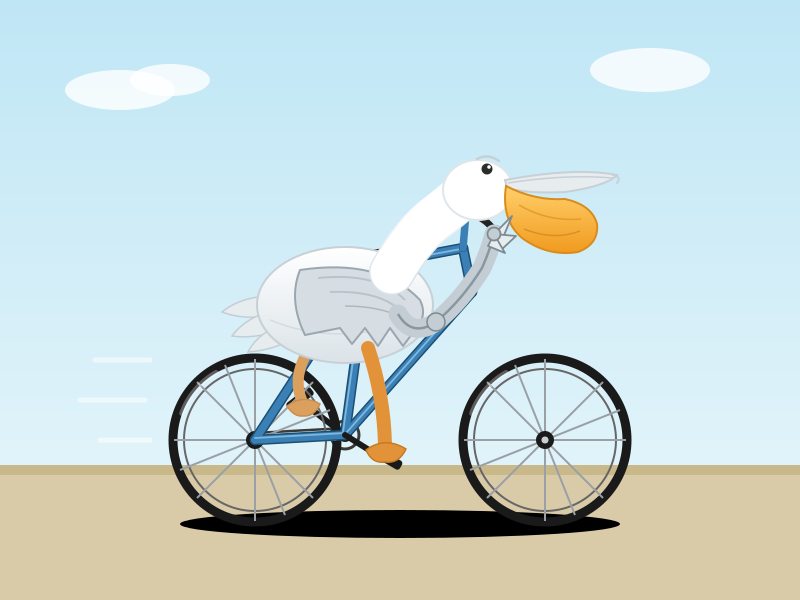
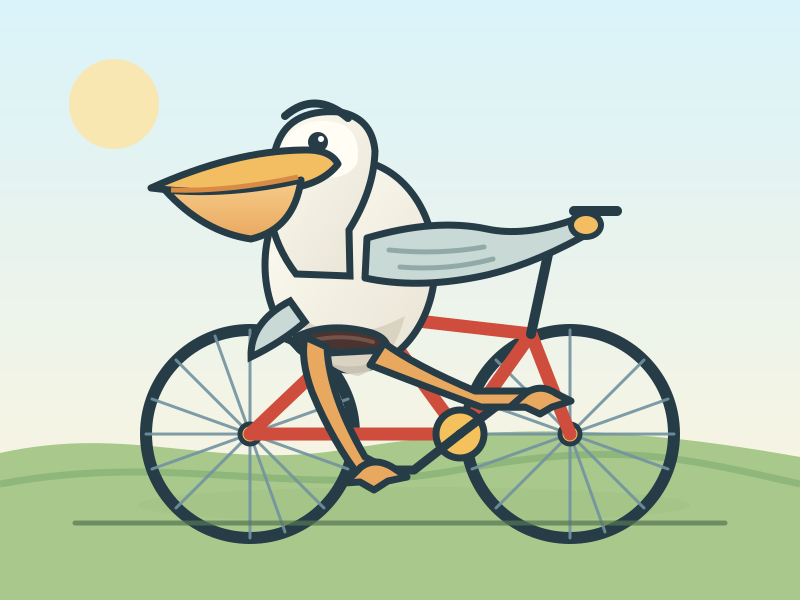
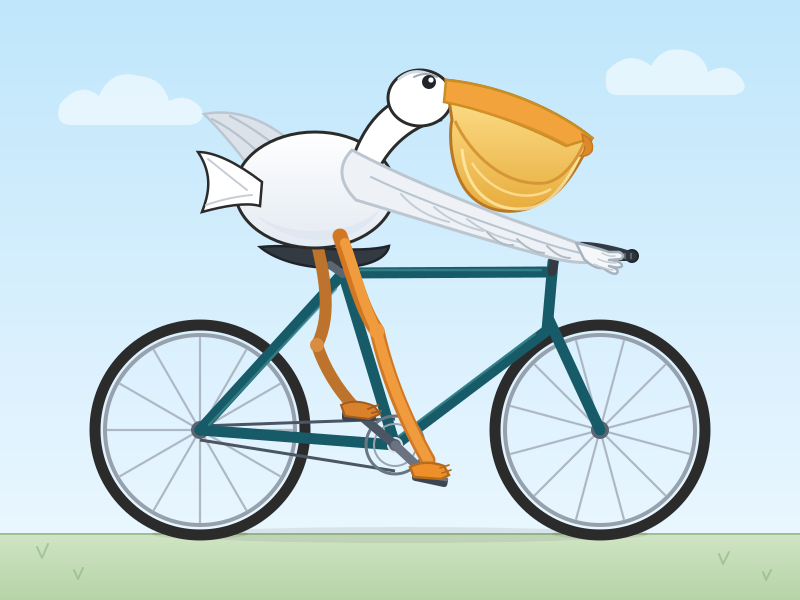
Five agent and model pairs, all routed through OpenRouter in the jettygrowthteam collection. Each hill-climbed from the same v1 runbook for up to five rounds (Gemini 3.8 Flash stopped after one: two OpenRouter outages). Every image below is that agent's own pick for its best round.
Where the v2 birds are strong and weak
External judge score per rubric axis (0–10), best round per agent. Hover an axis for values.
claude-code · Opus 5.5claude-code · Sonnet 5opencode · GPT-5.6 Terraopencode · Gemini 3.8 Flashhermes · Jev Router
Show as table
| Agent | Pelican | Bicycle | Composition | Polish | Total |
|---|---|---|---|---|---|
| claude-code · Opus 5.5 | 8.5 | 8 | 8.3 | 8 | 32.8 |
| claude-code · Sonnet 5 | 7.5 | 5 | 6.5 | 6.3 | 25.3 |
| opencode · GPT-5.6 Terra | 7.2 | 6.5 | 7.2 | 7.2 | 28 |
| opencode · Gemini 3.8 Flash | 8.7 | 7.7 | 8 | 8.5 | 32.8 |
| hermes · Jev Router | 8 | 7.7 | 8.3 | 7.7 | 31.7 |
Agents grade themselves generously
Same drawing, two scores out of 40: the agent's self-score and an external judge (Claude Opus 5.5, temperature 0, three samples averaged). Click a row to open that agent.
external judgeagent self-score
Show as table
| Agent | Cohort | Judge | Self-score | Inflation |
|---|---|---|---|---|
| opencode · Gemini 3.8 Flash | v2 | 32.8 | 38.5 | +5.7 |
| claude-code · Opus 5.5 | v2 | 32.8 | 36 | +3.2 |
| hermes · Jev Router | v2 | 31.7 | 37 | +5.3 |
| gemini-cli · Gemini 3.5 Flash | v1 | 29.8 | 40 | +10.2 |
| opencode · Gemini 3.5 Flash | v1 | 29.3 | 40 | +10.7 |
| hermes · Fusion router | v1 | 28.8 | 34 | +5.2 |
| claude-code · Opus 4.7 | v1 | 28.7 | 36 | +7.3 |
| opencode · Fusion router | v1 | 28.3 | 36 | +7.7 |
| hermes · Gemini 3.5 Flash | v1 | 28.2 | 39.5 | +11.3 |
| opencode · GPT-5.6 Terra | v2 | 28 | 38 | +10 |
| hermes · GLM 5.1 | v1 | 27.3 | 36.5 | +9.2 |
| claude-code · Sonnet 4.6 | v1 | 26.2 | 37 | +10.8 |
| claude-code · Sonnet 5 | v2 | 25.3 | 36 | +10.7 |
| hermes · Sonnet 4.6 | v1 | 24 | 36 | +12 |
What the judge changed
Findings
All numbers are computed from the published data (results.json).
Self-scores climb. The judge's mostly don't.
Across 13 lineages with three or more rounds, the agents' self-scores rose by 2.3 points on average from round 1 to their best, while the judge's score for the last round was 0.9 points lower than round 1. 8 of 13 ended below where they started by the judge's measure. The steepest slide: hermes · Sonnet 4.6, from 26.5 to 19.8.
A self-score barely predicts the judge's
Over all 98 scored drawings the correlation between self-score and judge score is 0.28. The hill climb steers by the self-score (it targets the weakest self-scored axis), so it is steering by an instrument that only loosely tracks what a viewer sees. That's the likeliest reason long climbs drift.
Some agents are much kinder to themselves
hermes · Sonnet 4.6 gave its best round 36/40; the judge gave it 24 (+12). The most honest was claude-code · Opus 5.5: 36 self vs 32.8 judge (+3.2). Gemini Flash lineages in v1 awarded themselves 39.5 to 40.
Current models draw better pelicans
The v2 cohort averages 30.1/40 from the judge against 27.9 for v1. Best v2: opencode · Gemini 3.8 Flash at 32.8. Best v1: gemini-cli · Gemini 3.5 Flash at 29.8. v2 did this in five rounds instead of ten.
Explore
Every image links back to the Jetty trajectory that produced it. v1 runs live in the jettyio collection, v2 runs in jettygrowthteam.
Leaderboard
All lineages ranked by the judge, with radar charts per agent and every hill-climb curve.
Head-to-head
Step through every round of every agent's hill climb. Arrow keys work.
Judge vs self-score
How we re-scored every drawing with one external vision judge, and how far the self-scores drift.
Runbook diffs
Diff any two runbook versions in any lineage, from Jon's hand edits to the auto-evolved rounds.
Method
The task, the rubric, the hill-climb loop and what we learned from the v1 hand-curated climb.
Run it yourself
The runbook, the Jetty task JSON and a curl command to run it in your own collection.
Inspired by Simon Willison's pelican-riding-a-bicycle benchmark.
FAQ
Pelican benchmark: questions and answers
Which AI agent draws the best pelican riding a bicycle?
Scored by one external vision judge (Claude Opus 5.5, temperature 0, three samples averaged, four axes of 0–10), the best drawings came from: opencode · Gemini 3.8 Flash 32.8/40; claude-code · Opus 5.5 32.8/40; hermes · Jev Router 31.7/40. Scores are each agent's best round after hill-climbing on Jetty.
Do coding agents grade their own drawings accurately?
No. Across 14 agent and model pairs, the median agent scored its own best drawing 9.6 points (out of 40) higher than the external judge did, and self-scores kept rising during hill-climbing while judge scores did not.
How is the pelican benchmark scored?
Each drawing is a hand-written SVG (800x600, under 50 KB, no embedded images). It is scored on four axes: Pelican, Bicycle, Composition and Polish, 0 to 10 each, for a maximum of 40, both by the agent itself and by an external vision judge.
Can I run the pelican benchmark myself?
Yes. It is a Jetty runbook (pelican-bicycle-svg). Copy it into your Jetty collection, add an OPENROUTER_API_KEY, and run it with any supported agent and model. Instructions: evaljetty.com/pelicans/run.html.