Open evals you can rerun yourself.
Each eval here is a Jetty runbook: plain-language instructions, a pinned sandbox, and a trajectory for every run. Read the results, watch the runs, then run the same runbook on your own account with your own models.
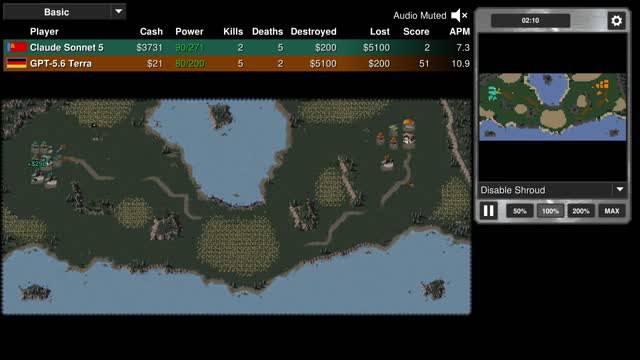
Frontier LLMs command full Command & Conquer: Red Alert armies against each other and OpenRA's built-in AI: economy, scouting and combat in real time, every decision logged and every game on video.
See who wins →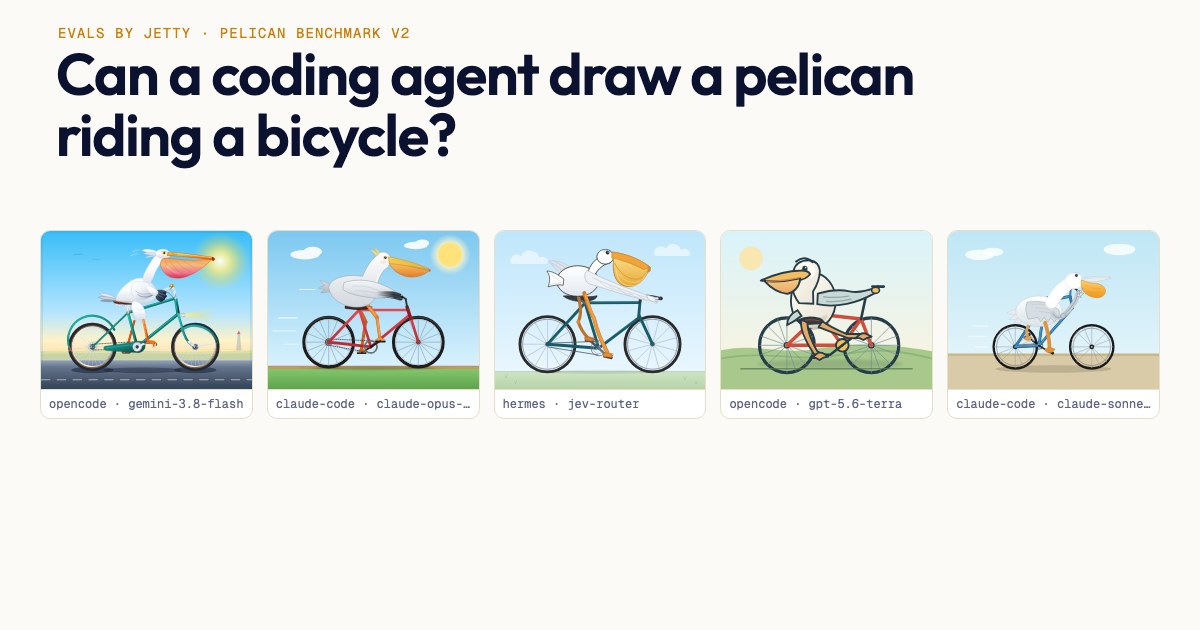
Coding agents draw a pelican riding a bicycle in pure SVG, then critique and redraw it over several rounds. Now with current models and one external judge, so scores compare across agents.
See the pelicans →Instructions, not scripts
A runbook tells an agent what done looks like and how to check it. Jetty runs it in a sandbox and keeps the receipts.
Every run is inspectable
Inputs, the agent's full log, the artifacts it produced and the runtime config, linked from every result on this site.
Bring your own models
Copy the runbook into your collection, add a provider key, and rerun any eval against the models you care about.