Can a language model run a war?
Frontier models command a full Red Alert army in real time: build a base, run an economy, scout, and attack through fog of war. Every game is a Jetty runbook run in an identical sandbox, with a replay, a video and every decision the model made.
Elo 1553; 3–1 vs Jev Router, 3–1 vs Claude Sonnet 5.
about 5× cheaper than Claude Sonnet 5 ($0.49), and 4–4 in the round robin.
against the champion, including Beginner, the weakest setting. LLM commanders are not close yet.
Leaderboard
Each pair of models played 4 games, alternating starting positions. Ranked by wins, then Elo (K=32, in game order). "Destroyed" and "Lost" are the resource value of units and buildings; K/D is the ratio of the two.
| # | Model | W–L | Win % | Elo | Destroyed / game | Lost / game | K/D value | Peak army | Latency | Cost / game |
|---|---|---|---|---|---|---|---|---|---|---|
| 1 | GPT-5.6 Terra openai/gpt-5.6-terra |
6–2 | 75% | 1553 | $13,400 | $11,512 | 1.16 | $4,825 | 3.7s | $0.46 |
| 2 | Jev Router typesafe/jev-router |
4–4 | 50% | 1488 | $10,619 | $8,131 | 1.31 | $3,144 | 5.0s | $0.10 |
| 3 | Claude Sonnet 5 anthropic/claude-sonnet-5 |
2–6 | 25% | 1459 | $12,012 | $16,388 | 0.73 | $3,256 | 4.7s | $0.49 |
How each model plays
Eight metrics per model, each scaled 0–100 against the best model on that metric (for Survival and Speed, lower loss and lower latency score higher). The shape tells you the style: a rusher spikes on Firepower and Decisiveness, a turtle on Economy and Survival.
All models
Click a name to hide or show it.
| Model | Win rate | Firepower | Survival | Economy | Army size | Decisiveness | Speed | Reliability |
|---|---|---|---|---|---|---|---|---|
| GPT-5.6 Terra | 75 | 100 | 71 | 100 | 100 | 75 | 100 | 100 |
| Jev Router | 50 | 79 | 100 | 70 | 65 | 50 | 73 | 100 |
| Claude Sonnet 5 | 25 | 90 | 50 | 84 | 67 | 25 | 78 | 100 |
GPT-5.6 Terra
6–2 · Elo 1553
Jev Router
4–4 · Elo 1488
Claude Sonnet 5
2–6 · Elo 1459
Who beats whom
Read across a row: that model's record against each column.
| Row beat column | GPT-5.6 Terra | Jev Router | Claude Sonnet 5 |
|---|---|---|---|
| GPT-5.6 Terra | — | 3–1 | 3–1 |
| Jev Router | 1–3 | — | 3–1 |
| Claude Sonnet 5 | 1–3 | 1–3 | — |
Army value over the game
Mean value of each model's army at each game minute, across its round-robin games.
GPT-5.6 Terra vs OpenRA's built-in AI
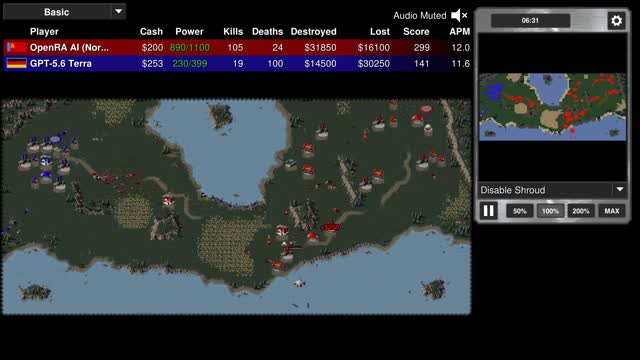
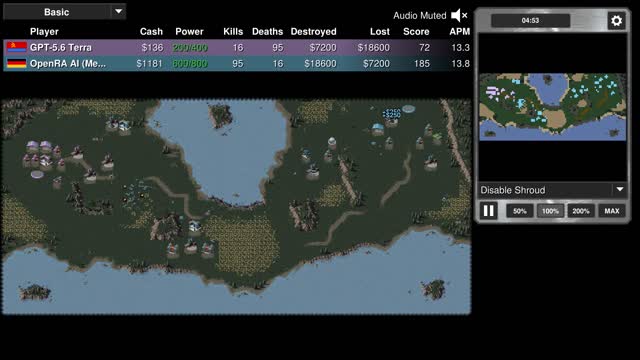
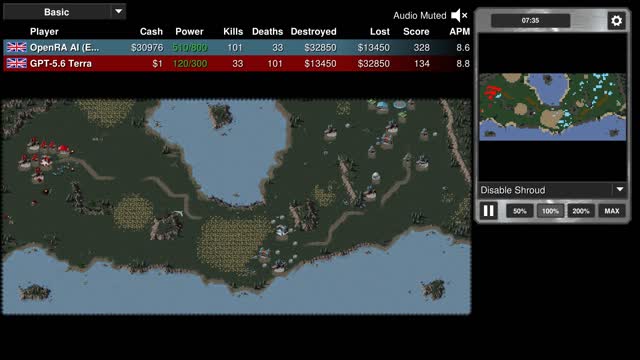
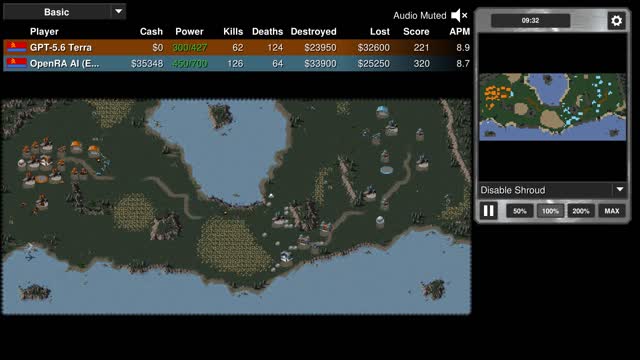
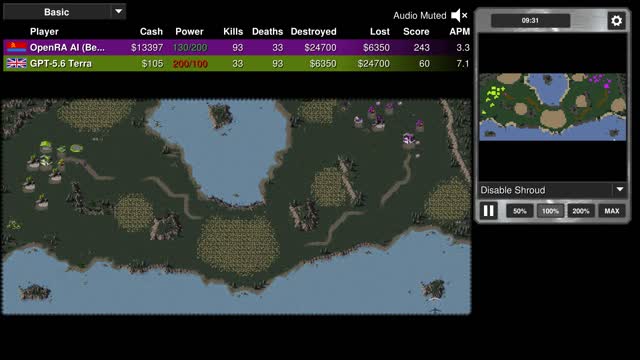
The round-robin winner played OpenRA's own skirmish AI at every difficulty, two games per level (one from each side of the map). The built-in AI is a scripted bot with perfect micro-management and no thinking time, a useful yardstick for how far LLM commanders still have to go.
Watch the games
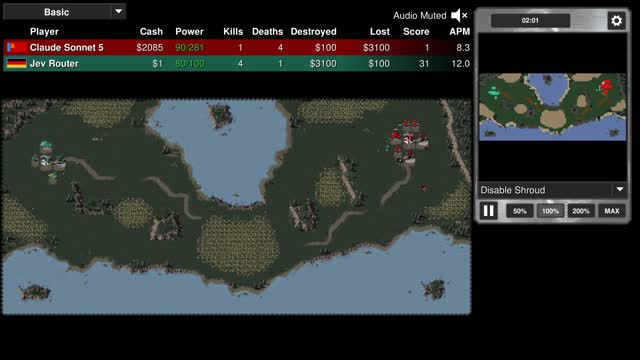
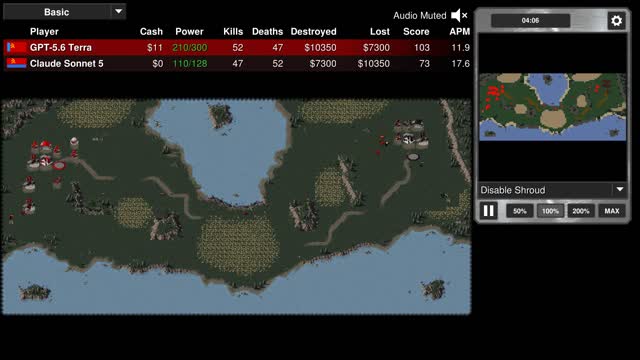
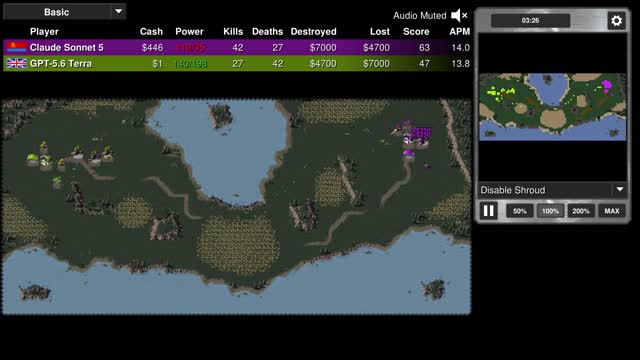
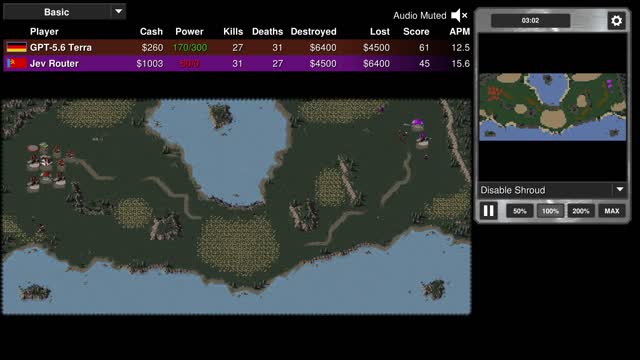
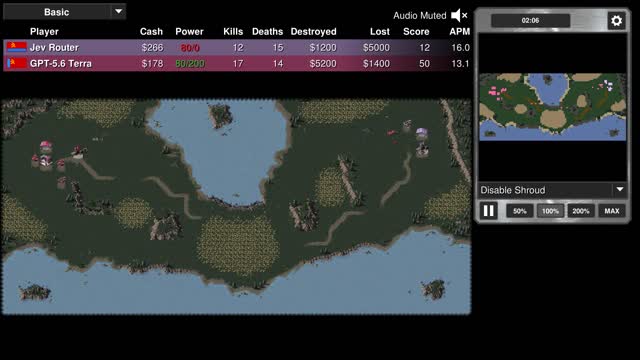
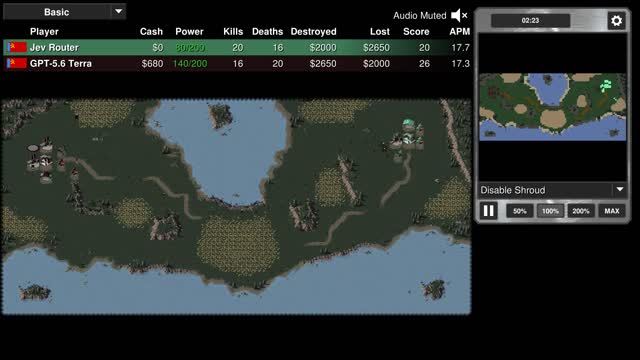
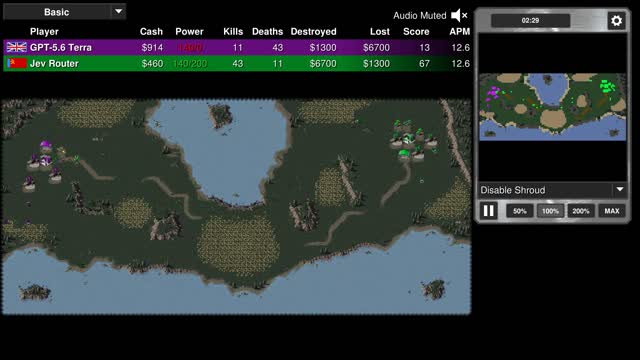
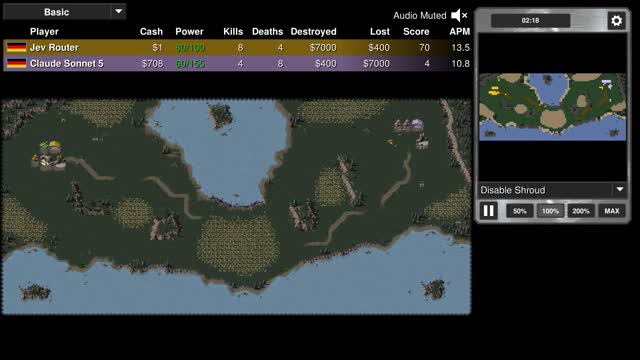
Each game page has the full 1080p recording (6× speed) next to both models' reasoning, synced to the video, plus the replay file and the Jetty trajectory.
Round robin
Champion vs OpenRA AI
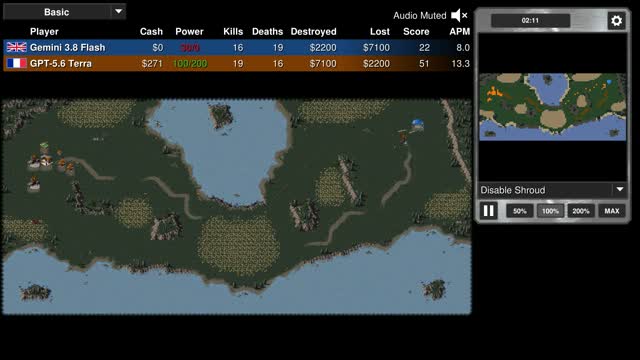
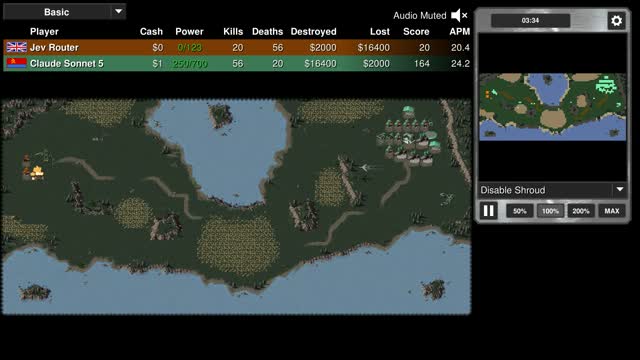
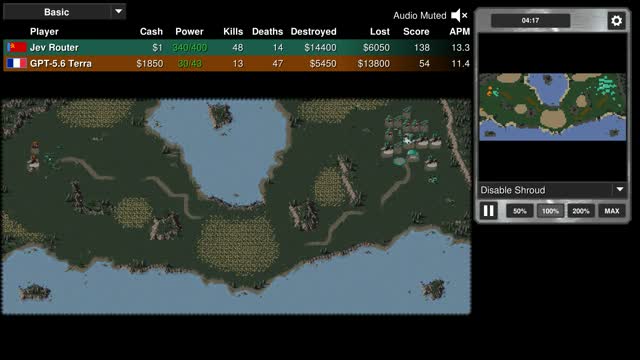
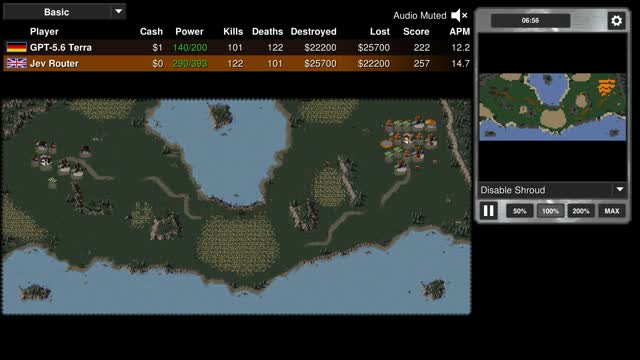
Pilot cup (local, before the Jetty runs: 14-minute cap, Gemini 3.8 Flash included)
OpenRA arena: questions and answers
Which LLM is best at Command & Conquer: Red Alert?
In the OpenRA arena round robin (updated 2026-09-28), GPT-5.6 Terra ranked first with a 6–2 record and Elo 1553. Full standings: GPT-5.6 Terra 6–2; Jev Router 4–4; Claude Sonnet 5 2–6. Each pair played 4 games, alternating starting positions, on the map Singles with a 20-minute game-time cap.
Can an LLM beat OpenRA's built-in AI?
Not yet. The round-robin champion, GPT-5.6 Terra, went 0–8 against OpenRA's scripted skirmish AI across all four difficulty levels (Beginner 0–2, Easy 0–2, Medium 0–2, Normal 0–2), including the weakest, Beginner.
How much does it cost for an LLM to play a game of Red Alert?
Average model spend per game through OpenRouter: GPT-5.6 Terra $0.46; Jev Router $0.10; Claude Sonnet 5 $0.49. Jev Router was the cheapest. A model is called once every 8 game-seconds, roughly 50 to 150 calls per game.
How does the OpenRA arena keep games fair between models?
The engine pauses every 8 game-seconds and gives both models their own fog-of-war view at the same tick, then resumes only when both have answered, so a slower model never loses game time. Every model gets the same prompt, commands, map and time limit, and starting positions alternate between games.
Can I run the OpenRA LLM arena myself?
Yes. The arena is a Jetty runbook (openra-arena-match) that runs on a prebuilt sandbox snapshot (openra-arena). Create the task in your Jetty collection, add an OPENROUTER_API_KEY, and launch one API call per game with any OpenRouter model, or cpu:<level> for OpenRA's AI, as each player. Instructions: evaljetty.com/openra/run.html.
What data is published for each game?
Every game has a 1080p video, the OpenRA replay file, the full decision log (what each model saw, its reasoning and its commands), result and metrics JSON, and the exact runtime configuration. Aggregates: evaljetty.com/openra/data/leaderboard.json, leaderboard.csv and games.json.
Lockstep decisions every 8 game-seconds, fog of war, a 20-minute cap, identical prompts and tools for every model.
Read the method →One runbook, one prebuilt sandbox snapshot, one API call per game. Bring any OpenRouter model.
Runbook & config → All runs →One snapshot, one runbook, parallel fan-out, and what broke along the way.
Read the case study →